~/projects/llm-from-scratch
GPT from Scratch
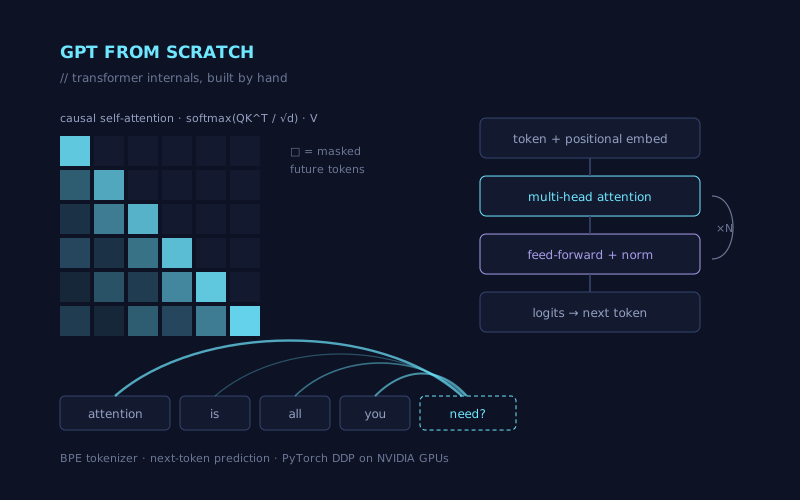
A ground-up implementation of a GPT-style language model built to understand transformer internals: multi-head self-attention, Byte Pair Encoding, GPU training, and RLHF-style fine-tuning. Developed in Jupyter notebooks with PyTorch on CUDA (via WSL2) and DDP support, the project prioritizes architectural clarity over rapid prototyping. Work in progress.
Highlights
- Multi-head attention transformer architecture modeled after GPT, with core LLM logic implemented from first principles
- PyTorch CUDA training through a WSL2 environment to leverage NVIDIA GPU compute
- Byte Pair Encoding (BPE) tokenizer and fine-tuned NLP embeddings for the initial vocabulary
- Output fine-tuning using an RLHF methodology
- Distributed training support with PyTorch DDP